TL;DR

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
Mistral says it has released updated weights for Mistral Large 4, its one-trillion-parameter multimodal model, after three additional weeks of reinforcement learning following a public preview. The company reports stronger coding results, lower token use on some benchmarks and a 96.6% refusal rate on tested malicious cyber prompts; those figures are company-reported and depend on the stated evaluations.
Mistral AI says it has released the weights for an updated version of Mistral Large 4, its one-trillion-parameter, natively multimodal model, following a public preview earlier this month. The company says three additional weeks of reinforcement learning improved coding and defensive cybersecurity performance while making reasoning more token-efficient; the release gives developers and organizations access to model weights they can deploy and customize.
Mistral describes the release as an improved version of Large 4, also called “Le Chonk.” The model entered public preview earlier this month. The company says it used feedback from developers, early-access customers and partners alongside further reinforcement learning before publishing the weights. The announcement does not specify a separate version number for the updated model.
For coding, Mistral reports a 19.7% score on Cognition’s private FrontierCode 2.0 benchmark, which evaluates end-to-end code quality and whether a repository maintainer would accept an agent’s changes. On Artificial Analysis’ Coding Agent Index, Mistral says Large 4 scored 48%, effectively tied with the leading open-weight model in that evaluation, while using an average of 47% fewer tokens per task. On Terminal-Bench 4.0, the company reports a 41% score, 13 percentage points above its public-preview result, and 30% fewer output tokens.
The release includes three reasoning modes: Low for simpler tasks, Medium for everyday use and High, the default, for demanding tasks requiring greater precision. Mistral says the modes let developers choose a balance between performance and inference cost. The model’s weights are available for self-hosted and customized deployment, though the announcement does not specify the exact license terms in the material provided here.
Lower Token Use for Coding Agents
The release matters to teams building coding agents and other AI applications because model weights can allow deployment and customization beyond a hosted service, subject to the applicable license and infrastructure needs. Mistral’s reported token-efficiency results may also matter for operating costs: its Coding Agent Index comparison says Large 4 used 47% fewer tokens per task on average than the leading open-weight model it compares against. That is a benchmark result, not a guarantee of lower costs in every deployment.
For security teams, the company’s claims address two competing needs: models that can assist with vulnerability discovery and patching, and safeguards against malicious cyber requests. Mistral reports a 51% Artificial Analysis Cyber Index score and an average 96.6% refusal rate on malicious cyber prompts in three named evaluations. Those results may inform assessments of the model, but they do not by themselves establish how it will behave across all real-world security work.
Mistral also presents the model as a sovereign AI option, saying it was trained from scratch on European infrastructure and has a clear lineage from development to release. That positioning is relevant to organizations seeking more control over where AI runs and how it is adapted. The announcement does not independently document those claims or detail the infrastructure and governance arrangements.
Products Worth Considering

Samsung 27-Inch Odyssey QD-OLED G8 4K 240Hz Gaming Monitor

Apple iPad Air (2025) 13‑inch Wi‑Fi 256 GB – Space Gray (M3 chip)
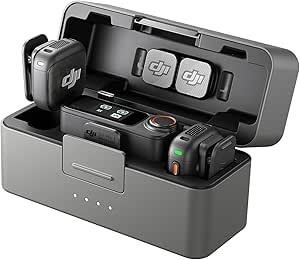
DJI Mic 3 Wireless Microphone System (2 Transmitters, 1 Receiver, Charging Case)
As an affiliate, we earn on qualifying purchases.
From Preview to Released Weights
Mistral says Large 4 was first made available in public preview earlier this month. Its latest announcement describes the weights as a subsequent release, after further reinforcement learning and feedback from early users. The company says it saw continuing coding gains during that work; this is its account of the development process, rather than an independently audited finding.
The model’s scale and design are central to Mistral’s pitch: it calls Large 4 a one-trillion-parameter, natively multimodal model and says the released weights give developers control to adapt and self-host it. Its benchmark evidence combines a private evaluation from Cognition, results attributed to Artificial Analysis, and human preference tests from Surge Code. Results from different benchmarks measure different tasks and should not be treated as interchangeable measures of overall capability.
Mistral says Surge Code’s blind pairwise evaluations preferred Large 4 over several open-weight competitors, while placing it behind Claude Opus 5.5 among the models tested. The announcement also says the model distinguishes defensive from offensive cybersecurity tasks. Such vendor-reported comparisons provide a basis for evaluation, but the supplied material does not include full test protocols or independent replication.
“Today, we’re releasing the weights of this improved Mistral Large 4.”
— Mistral AI
Licensing and Independent Testing
The supplied announcement does not state the precise license terms, where developers can obtain the weights, or what hardware and serving requirements are needed to run the model. Those details matter to organizations deciding whether they can use, modify or redistribute it and what deployment will cost.
The performance figures are presented by Mistral with references to named benchmarks and evaluators. The material provided does not include complete methodologies, confidence ranges or independent replications. It is also unclear how the reported gains translate to different languages, codebases, security environments and production workloads. Mistral’s 96.6% malicious-prompt refusal rate reflects tests on prompts from JailbreakBench, StrongREJECT and AgentHarm, not every possible harmful request.
Access and Real-World Evaluation
Developers and organizations can now assess the released weights against their own tasks, subject to availability and licensing terms. The next useful evidence will come from detailed documentation of access, license, deployment requirements and evaluation methods, as well as independent tests and reports from users running the model in production.
Mistral says it will continue scaling reinforcement learning and working with cybersecurity vendors. It has not announced a date for a later model update or a further benchmark release in the supplied material. Until those details emerge, the company’s published comparisons remain an initial basis for judging the updated model rather than a settled account of its performance across deployments.
Key Questions
What has Mistral released?
Mistral says it has released the updated weights for Mistral Large 4, a one-trillion-parameter, natively multimodal model that was previously in public preview.
What coding results does Mistral report?
The company reports a 19.7% score on Cognition’s private FrontierCode 2.0 benchmark, a 48% score on Artificial Analysis’ Coding Agent Index and a 41% score on Terminal-Bench 4.0. These are results on different evaluations, not a single general measure of coding ability.
What reasoning modes are available?
Mistral lists Low, Medium and High modes. It recommends Low for simpler tasks, Medium for everyday work and High, the default, for demanding tasks that require greater precision.
What does Mistral report about cybersecurity safeguards?
Mistral reports a 51% score on the Artificial Analysis Cyber Index and a 96.6% average refusal rate on tested malicious cyber prompts. Those figures apply to the named evaluations and do not establish behavior on every cybersecurity request.
Are the licensing and deployment details confirmed?
The supplied announcement says the weights are released and describes self-hosted customization, but it does not provide the exact license terms, access instructions or hardware requirements. Those details remain to be confirmed from the release documentation.
Source: mistral.ai