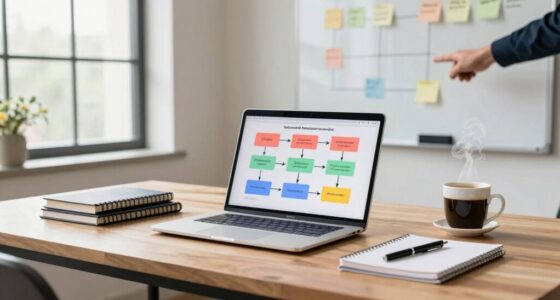
To effectively monitor workflow failures and alerts, you should implement automated diagnostics that detect issues as they happen. These tools analyze logs, metrics, and data points to identify anomalies like long processing times or repeated errors. By integrating root cause analysis, you can quickly determine why failures occur and address systemic issues proactively. Continuing to explore these strategies will help you build more reliable processes and minimize downtime efficiently.
Listen free for 30 days with Audible
Thousands of audiobooks and originals — cancel anytime.
As an affiliate, we earn on qualifying purchases.
Key Takeaways
- Implement automated alerting systems that notify teams immediately upon workflow failures for prompt response.
- Use diagnostic tools to automatically detect anomalies and deviations in process metrics.
- Conduct root cause analysis to quickly identify underlying issues behind workflow failures.
- Continuously monitor key performance indicators and error patterns to anticipate potential failures.
- Integrate detailed alerts with contextual information to prioritize issues and streamline troubleshooting.
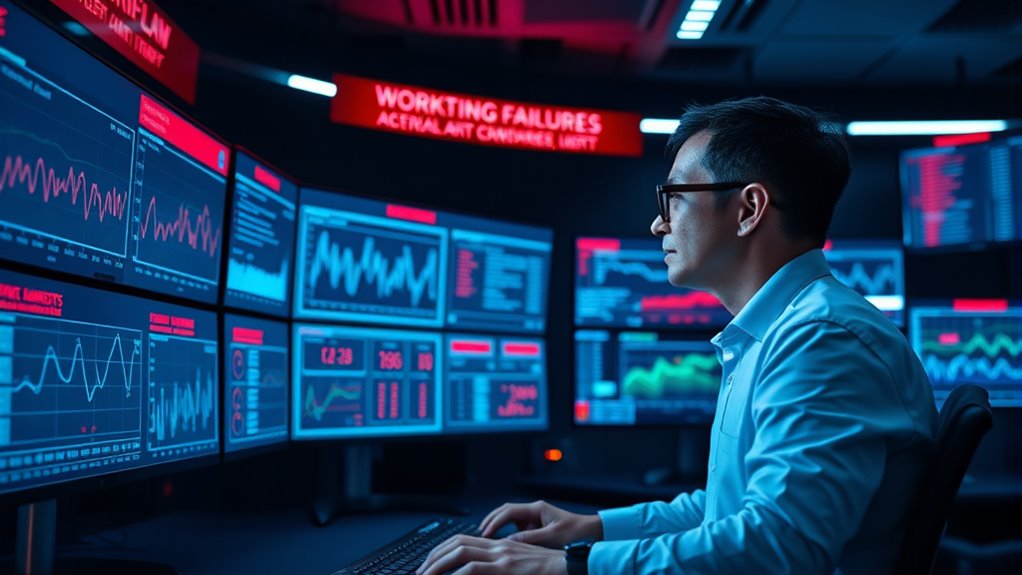
Monitoring workflow failures and alerts is essential for maintaining the reliability and efficiency of your processes. When a failure occurs, quick detection and resolution can prevent costly downtime and data loss. Automated diagnostics play a *vital* role here, enabling your system to automatically identify issues as they happen. This proactive approach means you can respond well before small issues escalate into major failures, saving time and resources.
Automated diagnostics enable quick detection and resolution of workflow failures, preventing costly downtime and data loss.
Effective monitoring isn’t just about catching failures; it’s also about understanding why they happen. This is where root cause analysis becomes invaluable. When an alert fires, you want to know the underlying reason—was there a misconfiguration, a data inconsistency, or a system overload? Automated diagnostics facilitate root cause analysis by correlating various data points, logs, and metrics. They help you trace the failure back to its source quickly, avoiding the trap of addressing symptoms instead of the actual problem.
By integrating root cause analysis into your alerting system, you gain the ability to not only react faster but also improve future workflows by addressing systemic issues. Implementing automated diagnostics means setting up systems that continuously monitor key performance indicators and error patterns. These diagnostics can detect subtle deviations from normal behavior that might be missed by manual checks.
For example, if a specific step in your workflow starts taking longer than usual or if a particular process fails repeatedly, the diagnostics flag these anomalies automatically. The system then generates alerts with detailed context, making it easier for you to understand the scope and severity of the problem immediately. This real-time insight helps you prioritize issues effectively, ensuring critical failures don’t slip through the cracks.
Moreover, integrating root cause analysis into your monitoring framework enhances your ability to prevent future failures. Once you identify the root cause of a recurring problem, you can implement targeted fixes rather than generic patchwork solutions. Over time, this leads to more resilient workflows and fewer disruptions.
Automated diagnostics and root cause analysis also facilitate collaboration among your team members by providing clear, structured data on failures. Instead of lengthy troubleshooting sessions, everyone can access precise insights, speeding up resolution times.
Additionally, understanding the importance of contrast ratio in your system’s visual outputs can help optimize performance and image quality, ensuring that your workflows not only run smoothly but also deliver the best possible results.
Frequently Asked Questions
How Can I Prevent False Alarms in Workflow Alerts?
To prevent false alarms in workflow alerts, you should focus on alert tuning and false alarm reduction strategies.
Fine-tune your alert thresholds to match normal variations in your workflow, avoiding overly sensitive settings.
Regularly review alert data to identify patterns that cause false alarms, then adjust parameters accordingly.
Implementing smarter alert rules and thresholds helps guarantee you only get notified for genuine issues, reducing unnecessary disruptions.
What Are the Best Tools for Real-Time Failure Detection?
You should use tools like Datadog, New Relic, or PagerDuty to detect real-time failures. These tools analyze failure patterns and set alert thresholds to identify issues quickly, reducing false alarms.
They offer customizable monitoring dashboards and anomaly detection, ensuring you get timely alerts when failures occur. By adjusting alert thresholds based on failure patterns, you can improve accuracy and respond swiftly to critical workflow disruptions.
How Do I Prioritize Alerts Based on Severity?
You should start with alert prioritization by evaluating each alert’s severity, considering factors like impact and urgency. Use severity assessment to categorize alerts into critical, high, medium, or low levels.
Then, focus on resolving the most severe issues first to minimize workflow disruption. Automate this process where possible, leveraging tools that support severity tagging, so you can quickly identify and address the most pressing failures.
What Are Common Causes of Workflow Failures?
You might wonder what causes workflow failures to suddenly strike. Common culprits include workflow bottlenecks that slow processes to a crawl and dependency issues where a single failure cascades through the system.
These problems can be subtle but devastating, causing tasks to stall or crash unexpectedly. Staying vigilant helps you identify these root causes early, ensuring smoother operations and preventing minor glitches from snowballing into major disruptions.
How Can I Automate Recovery Processes for Failures?
You can automate recovery processes by implementing failure prediction tools that detect issues early and trigger automated rollback procedures. Set up your workflow to automatically revert to a stable state when failures occur, reducing downtime.
Integrate monitoring systems with your automation scripts so they respond instantly to alerts. This proactive approach minimizes manual intervention, guarantees smoother recovery, and maintains workflow stability even during unexpected failures.
Conclusion
Just as Icarus learned, ignoring warning signs can lead to downfall. By actively monitoring workflow failures and setting timely alerts, you stay grounded and avoid unexpected crashes. Think of it as your steady compass in a stormy sea—guiding you away from disaster and toward smooth sailing. Remember, vigilance today keeps your operations soaring tomorrow. So, stay alert, act promptly, and keep your workflow flying high without falling into the trap of neglect.
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.