🔍 Read the full analysis: How A Neural Network Recognizes A Handwritten 7, Step By Step on ThorstenMeyerAI.com

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
TL;DR
A neural network classifies a handwritten digit by transforming pixel values through layers of weighted sums, biases and activation functions. The source article illustrates the process with a 28-by-28 image and a small XOR network, while noting that the digit model’s 109,386 parameters are mostly in its first layer.
A neural-network explainer published November 8 traces how a model can classify a handwritten seven, from the image’s 784 pixel values to the digit scores at the output. The account shows that each layer applies arithmetic operations to learned numbers, making the process inspectable even when a full network contains 109,386 parameters, as explored in work on neural network weights.
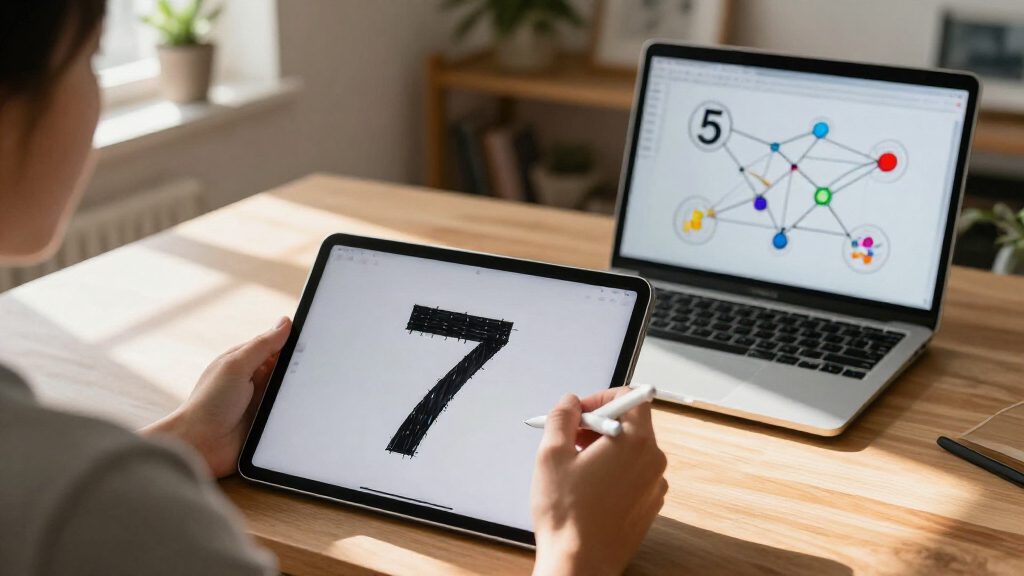
In the example, a 28-by-28 image is flattened into a list of 784 pixel values. The input layer holds those values and passes them along; it does not transform them. In a dense layer, each neuron multiplies inputs by weights, adds a bias, and applies an activation function. The resulting values become the next layer’s inputs.
The output layer returns 10 scores, one for each possible digit. The predicted digit is the one with the highest score, a basic idea behind AI systems such as those discussed in AI development. That describes the calculation, but not how the model learned the relevant weights: the source gives a small, hand-designed example to make the arithmetic concrete, rather than documenting the training of a particular digit-recognition model.
That example is a network for XOR, which returns one when two input bits differ. It uses two inputs, two hidden neurons and one output neuron, with nine numbers across its weights and biases. Using a step activation, the article shows how the hidden units’ outputs combine to produce the XOR result. Changing the output bias from −2 to −1 makes the network return one for all four possible input pairs.
Infographic 01 · One bias, two behaviors
A network you can run by hand
Two hidden neurons check "at least one bit is on" and "at most one bit is on". The output neuron needs both. Change its bias and it needs only one.
Move the output bias from −2 to −1 and the network stops computing XOR: it returns 1 for all four inputs.
The whole network
Hidden 1: step( x₁ + x₂ − 1 )
Hidden 2: step(−x₁ − x₂ + 1 )
Output:   step( h₁ + h₂ − 2 )
step: 1 if the total is zero or greater, otherwise 0. Nine numbers in total: six in the hidden layer, three in the output neuron.
All four inputs
Hidden outputs and the final output with the original and the changed bias
| Input | At least one | At most one | Output, bias −2 | Output, bias −1 |
|---|---|---|---|---|
| 0, 0 | 0 | 1 | 0 | 1 |
| 0, 1 | 1 | 1 | 1 | 1 |
| 1, 0 | 1 | 1 | 1 | 1 |
| 1, 1 | 1 | 0 | 0 | 1 |
Sources: own arithmetic, checked with a script · the XOR example as in Goodfellow, Bengio, Courville: Deep Learning, ch. 6.
Powered by Thorsten Meyer AI
Why the Weight Count Matters
The examples make two points relevant to understanding AI systems. First, a prediction can be followed through a sequence of specific arithmetic operations; calling a network a “black box” does not mean that its internal computations are inaccessible. Second, knowing the operations is not the same as finding a simple explanation for a complex model’s behavior. In a trained network, a result may reflect patterns distributed across many weights and layers.
The source says the digit reader has 109,386 parameters, with about 92% in its first layer. That concentration follows from the dense-layer design described: every pixel connects to each of 128 units in the first layer. The figure illustrates why even a small model can involve many values, and why changing one parameter in a toy example is much easier to interpret than editing a trained model.
Products Worth Considering

Amazon Kindle Paperwhite Signature Edition (12th Generation, 2024), 32 GB, Metallic Raspberry

Bose QuietComfort Wireless Noise-Cancelling Headphones, Twilight Blue

LG UltraGear 32GX850A-B 32-inch 4K UHD OLED Gaming Monitor
As an affiliate, we earn on qualifying purchases.
From Pixels to Layered Calculations
The article focuses on a multilayer perceptron, a feedforward network built from dense layers. It represents a layer’s calculation as z = Wx + b, followed by an activation: the input vector x is multiplied by a weight matrix W, the bias vector b is added, and an activation turns those totals into outputs. Those outputs feed the next layer.
It also distinguishes choices made before training from values learned during training. Width and depth describe the number of units and layers; they are architectural choices. Weights and biases are model parameters that training normally adjusts, though they can also be assigned directly, as in the XOR demonstration. The source notes that researchers have observed early image-network layers responding to simple patterns and later layers to more complex features, but does not identify a particular study or model for that statement.
“A neural network is arithmetic in layers.”
— Thorsten Meyer, source article
What the Example Does Not Show
The source does not provide the digit model’s full architecture, its training data, its training process, or test results. It explains how a network computes a prediction, but does not show the internal values generated by a specific image of a handwritten seven or establish how accurate that model is.
The article also mentions a report from MIT CSAIL researchers about an AI model editing another network’s weights. It says one edit changed 0.016% of a language model’s weights and raised a math score from 7.9% to 48.1%. The source characterizes this as a blog post with public logs, not a peer-reviewed paper. The underlying evaluation details and the extent to which the result generalizes are not supplied here.
What Further Evidence Would Add
The next step for readers seeking to verify the digit example would be a full model specification, the image and its pixel values, and the scores produced at each layer. Training and evaluation details would help explain where the parameters came from and how reliably the classifier handles handwriting beyond a single example.
For the reported weight-editing result, the source points readers to public logs but gives no timetable for a peer-reviewed publication or further testing. Until more evidence is available, the result should be treated as a reported demonstration, separate from the basic, reproducible arithmetic in the XOR example.
Key Questions
How does a neural network recognize a handwritten 7?
It converts the image into pixel values, passes them through layers that apply weights, biases and activation functions, then selects the digit with the highest output score.
Does the input layer process the image?
In the dense-network example, the input layer holds and passes on the pixel values. The hidden layers perform the transformations.
What does changing one bias show?
In the small XOR network, changing the output bias from −2 to −1 changes its behavior so it returns one for all four input combinations. It is a deliberately simple example, not a description of how one weight typically controls a trained digit model.
How many parameters does the digit reader have?
The source describes a small digit reader with 109,386 parameters, about 92% of them in its first layer. It does not provide enough architectural detail here to independently verify the count.
Source: ThorstenMeyerAI.com